How to test an automation before you hand it to a client.
Every automation passes its demo. Production is a thousand submissions from strangers against data nobody chose, and that is where client trust is lost.
Every automation passes its demo. The demo is a single clean submission, run by the person who built the workflow, against data they chose. Production is a thousand submissions run by strangers against data nobody chose, and the difference between those two is where client trust is lost.
Testing an integration is not the same as testing a website. There is no visual regression to eyeball, the failure usually happens hours later, and the person who notices is the client. This is a practical order to work through before you hand anything over.
Test with data that looks like production, not like a demo.
Demo data is tidy because the person making it wanted the demo to work. Real submissions carry apostrophes in surnames, entire sentences typed into a name field, emails with plus signs, phone numbers written six different ways, and every optional field left empty.
If the client already has a system holding real records, ask for an anonymised export and test against a sample of it. Nothing you invent will be as hostile as what they already have. Where an export is not possible, build the awkward cases deliberately rather than hoping they do not arrive.
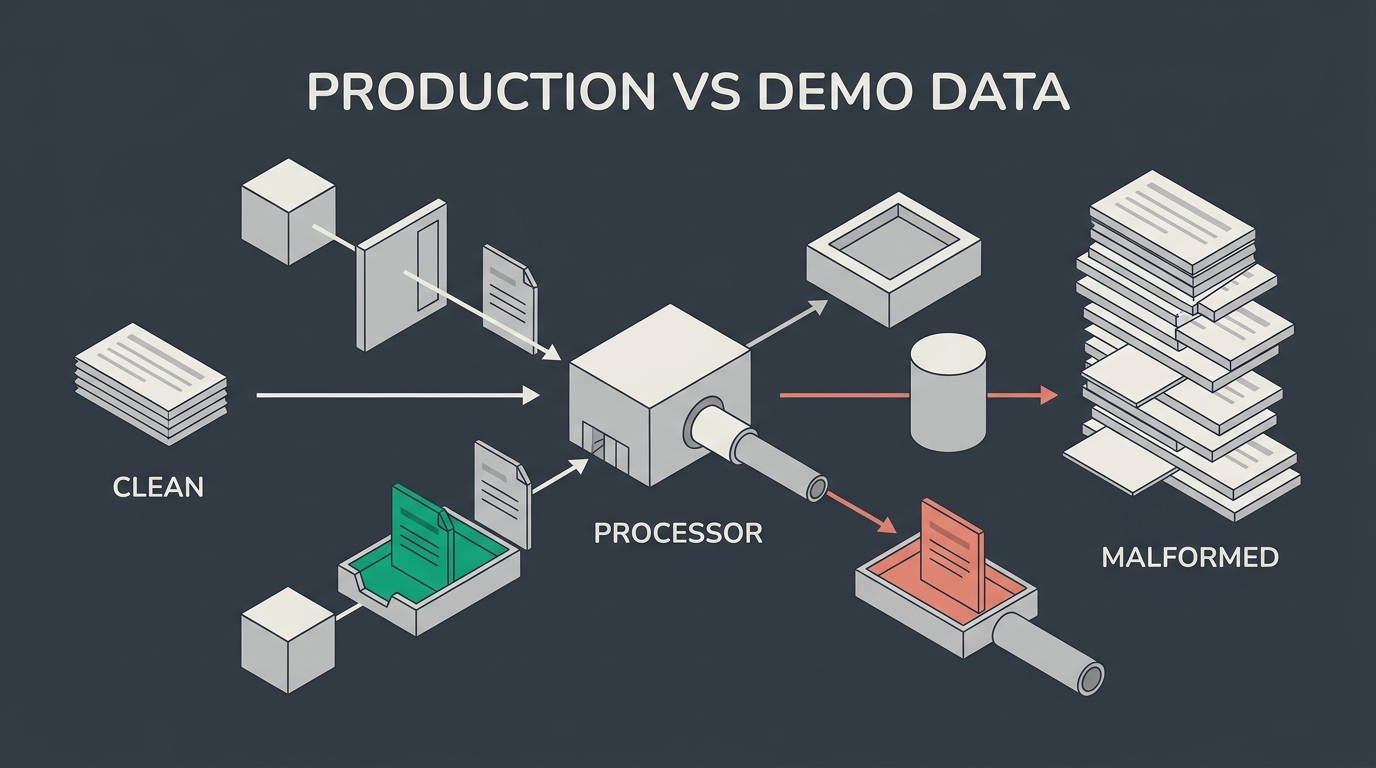
Separate the credentials before you separate anything else.
The most expensive testing mistake is writing test records into the client’s live CRM. It is expensive because it is not reversible in any tidy way, and because the client finds out by seeing them.
Use a separate sandbox account where the vendor offers one. Where they do not, use a distinct set of credentials with the narrowest possible permissions and a clearly marked test record you can find and delete afterwards. Write down which environment each credential points at, because the single most common cause of this failure is a workflow that was pointed at production during a debugging session and never pointed back.
Replay the payloads that actually arrive.
Do not hand-craft the trigger payload. Capture a real one.
Point the client’s form or system at a request-capture endpoint for a day, or log the raw body of the first genuine submissions before any parsing happens. Then replay those exact payloads into the workflow as often as you need. This finds two things a crafted payload never will: fields the vendor sends that nobody documented, and fields the vendor omits entirely when they are empty rather than sending them as blank.
The cases that decide whether it is ready.
Work through these before sign-off. Most take minutes and each one maps to a failure that would otherwise reach the client.
| Case | What you are proving |
|---|---|
| The same payload delivered twice | Deduplication holds and only one record is created |
| A required field empty | The workflow rejects cleanly instead of writing a broken record |
| Unicode, apostrophes, very long text | Nothing is truncated, mangled or fails to parse |
| A record that already exists downstream | The match rule attaches rather than duplicating |
| The destination API returning 429 | Backoff and retry work, and nothing is silently dropped |
| The destination API returning 500 or timing out | The run fails loudly rather than reporting success |
| An expired or revoked credential | Somebody is alerted rather than the workflow stopping quietly |
| Volume well above the expected peak | Rate limits and execution caps are not hit at real load |
| A failure between two writes | You can tell what completed, and re-running is safe |
The last row is the one most often skipped and the most damaging. If a workflow writes to two systems and dies between them, the client now has two systems disagreeing, and somebody has to work out what happened by hand.
Test the failure paths, not just the happy path.
A workflow that handles errors is only useful if the handling has been exercised. Cause each failure deliberately.
Revoke a token
Disable the credential and run the workflow. Confirm the alert fires, that it reaches a channel somebody actually reads, and that the message says which system failed and for which record. An alert nobody receives is the same as no alert.
Break the trigger
Disconnect the trigger entirely and confirm something notices. Error alerting only fires when a run fails, so it cannot detect a workflow that has stopped running altogether. That needs a separate heartbeat check, and this is the test that proves it exists.
Fill the queue
Send a burst of records and confirm the ones that could not be processed went somewhere a person will look, rather than being retried into oblivion.
Hand over evidence, not assurances.
“It has been tested” is not a deliverable. A short document listing what was tested, what the result was, and what is deliberately not handled is a deliverable, and it takes twenty minutes to write while the tests are still fresh.
Include the cases from the table above with a pass mark against each, the failure paths you triggered and what happened, the volumes you tested at, and an explicit list of the situations the workflow does not cover. That last list is the one clients and their future developers value most, and the one agencies are most reluctant to write.
It also protects you. A limitation stated in writing before handover is a scope boundary. The same limitation discovered afterwards is a defect.
One thing to check after go-live.
Testing ends at handover, but the first real week is still evidence. Agree with the client that somebody looks at the run history seven days in, counts the failures, and confirms the alerting fired for each one. Problems that only appear at real volume appear in that week, and finding them then is far cheaper than finding them in month three.
If you are about to hand over a client automation and you would rather someone else stress it first, send us the requirement and what it connects to. We will tell you which cases we would test and what we would expect to break. Send us the details and a person will read it.
Related notes
How to price ongoing automation maintenance.
Maintenance is a separate commercial product from the build, because you are selling availability rather than output. Price it against response, not hours.
How to integrate a system that has no API.
There is no API, or it costs more than the project. Five workable approaches, and how to choose the one that matches what the client can tolerate breaking.
How to handle GDPR when an automation moves client data.
Most agency automation work is data protection work, and it usually gets treated as though it is not. Controllers, processors and where the data actually goes.